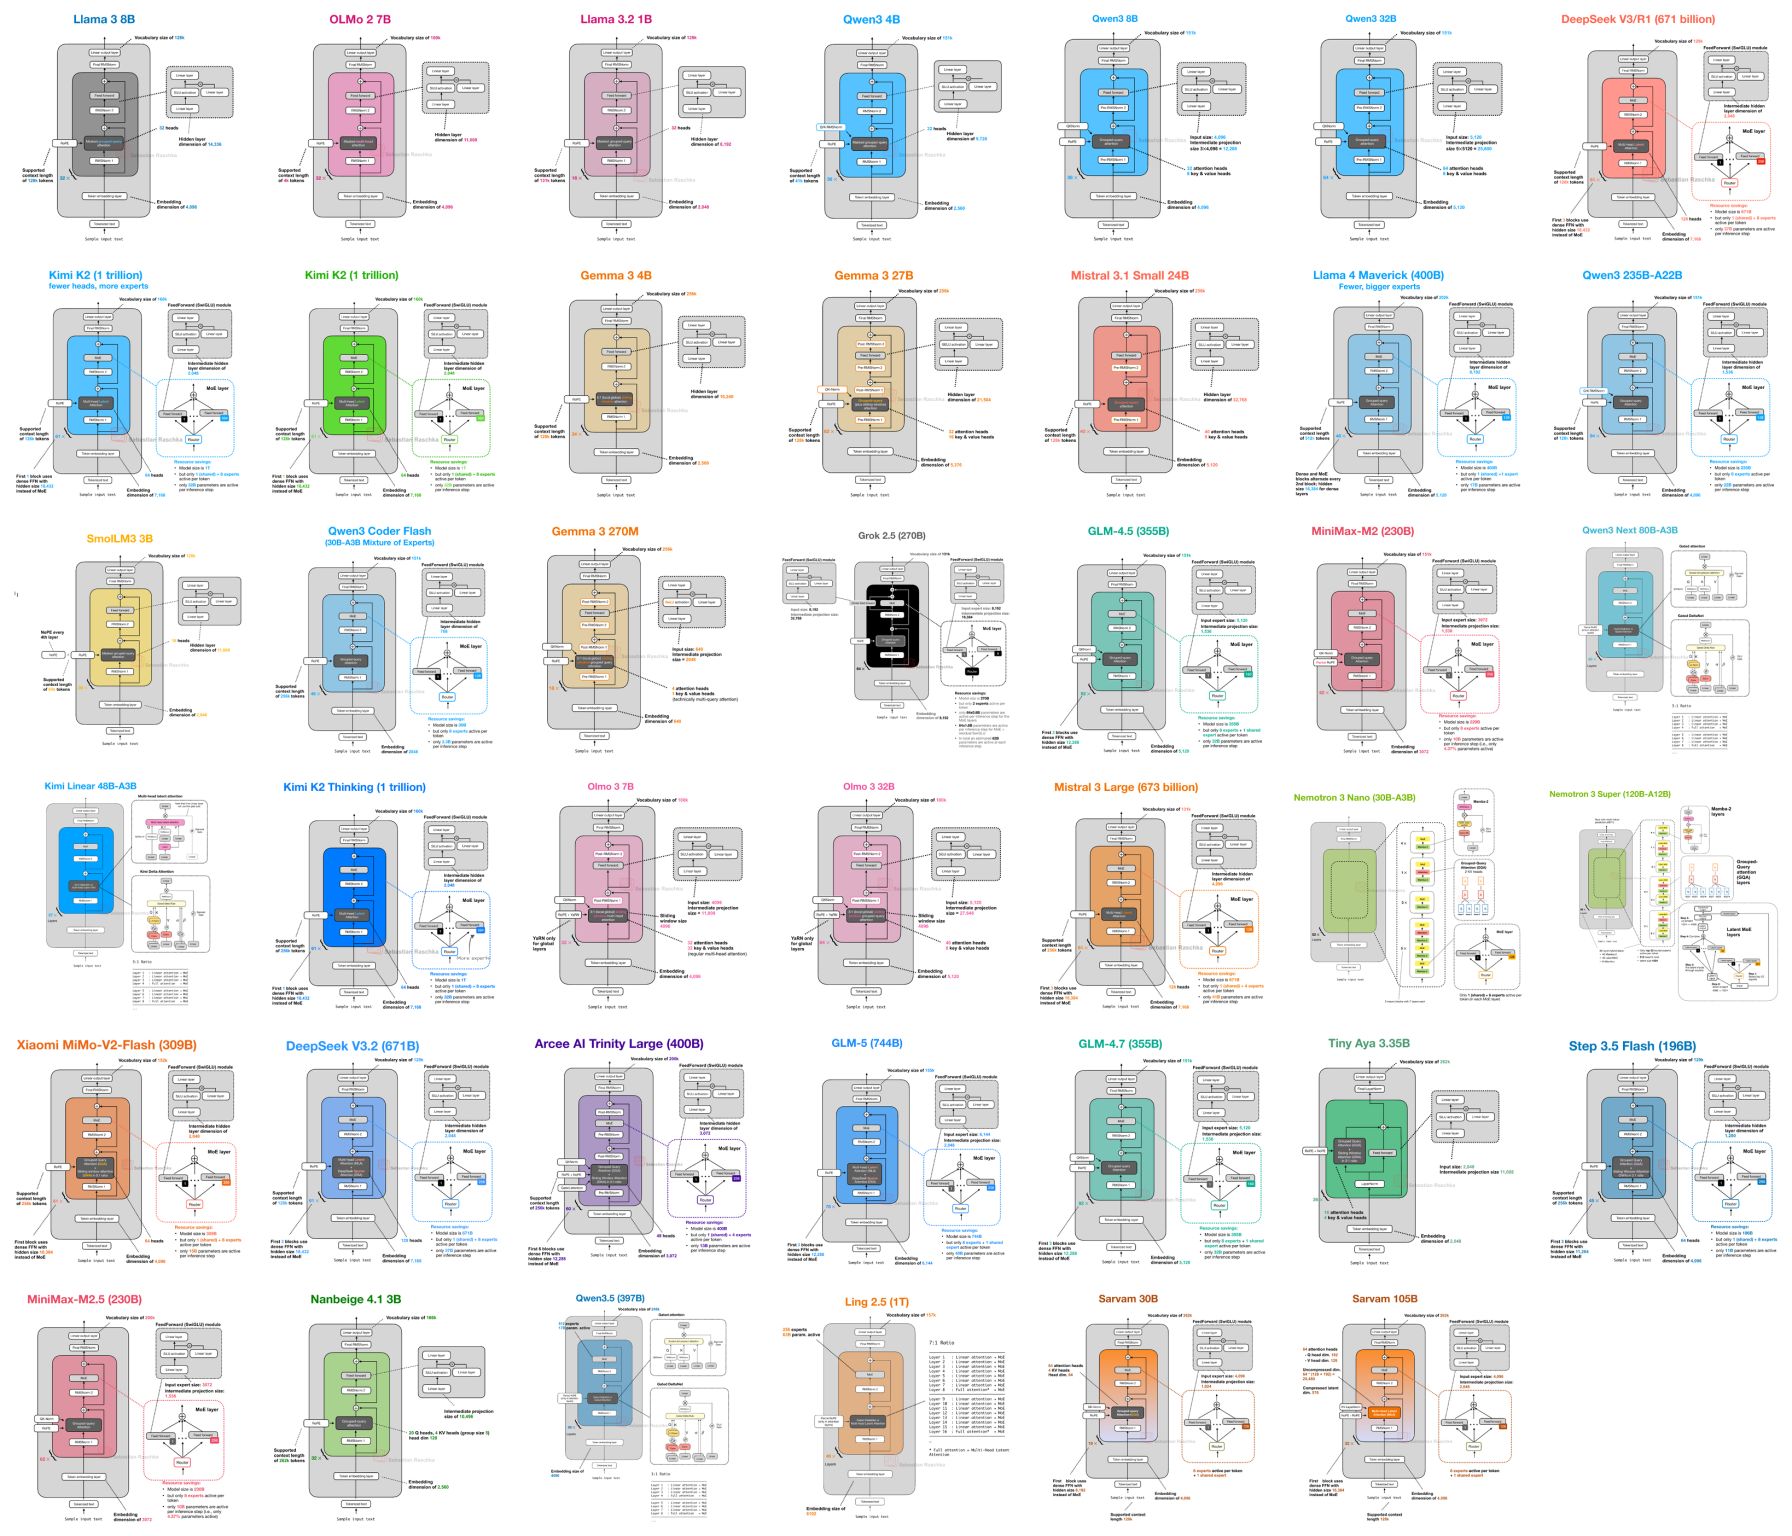
I put together a new LLM Architecture Gallery that collects the architecture figures I shared over the months and years in one place. The goal is to make it easier to quickly browse recent open-weigh…

LinkedIn Content Strategy & Writing Style
ML/AI research engineer. Author of Build a Large Language Model From Scratch (amzn.to/4fqvn0D) and Ahead of AI (magazine.sebastianraschka.com), on how LLMs work and the latest developments in the field.
1 person tracking this creator on ViralBrain
Sebastian Raschka positions himself as the premier educational architect of the LLM era, bridging the gap between high-level AI research and ground-level implementation. His content strategy centers on a "from-scratch" philosophy, where he deconstructs complex papers from labs like DeepSeek and NVIDIA into readable code, visual guides, and modular tutorials. He is notable for his ability to translate dense architectural shifts—such as Multi-Head Latent Attention or hybrid Mamba-Transformer stacks—into tangible engineering workflows that prioritize clarity over hype. By maintaining a unique intersection of academic rigor and open-source transparency, Raschka transforms the opaque "black box" of modern reasoning models into an accessible curriculum for the global developer community.
229.5K
1.3K
2.8K
1.7
118
7
I put together a new LLM Architecture Gallery that collects the architecture figures I shared over the months and years in one place. The goal is to make it easier to quickly browse recent open-weigh…

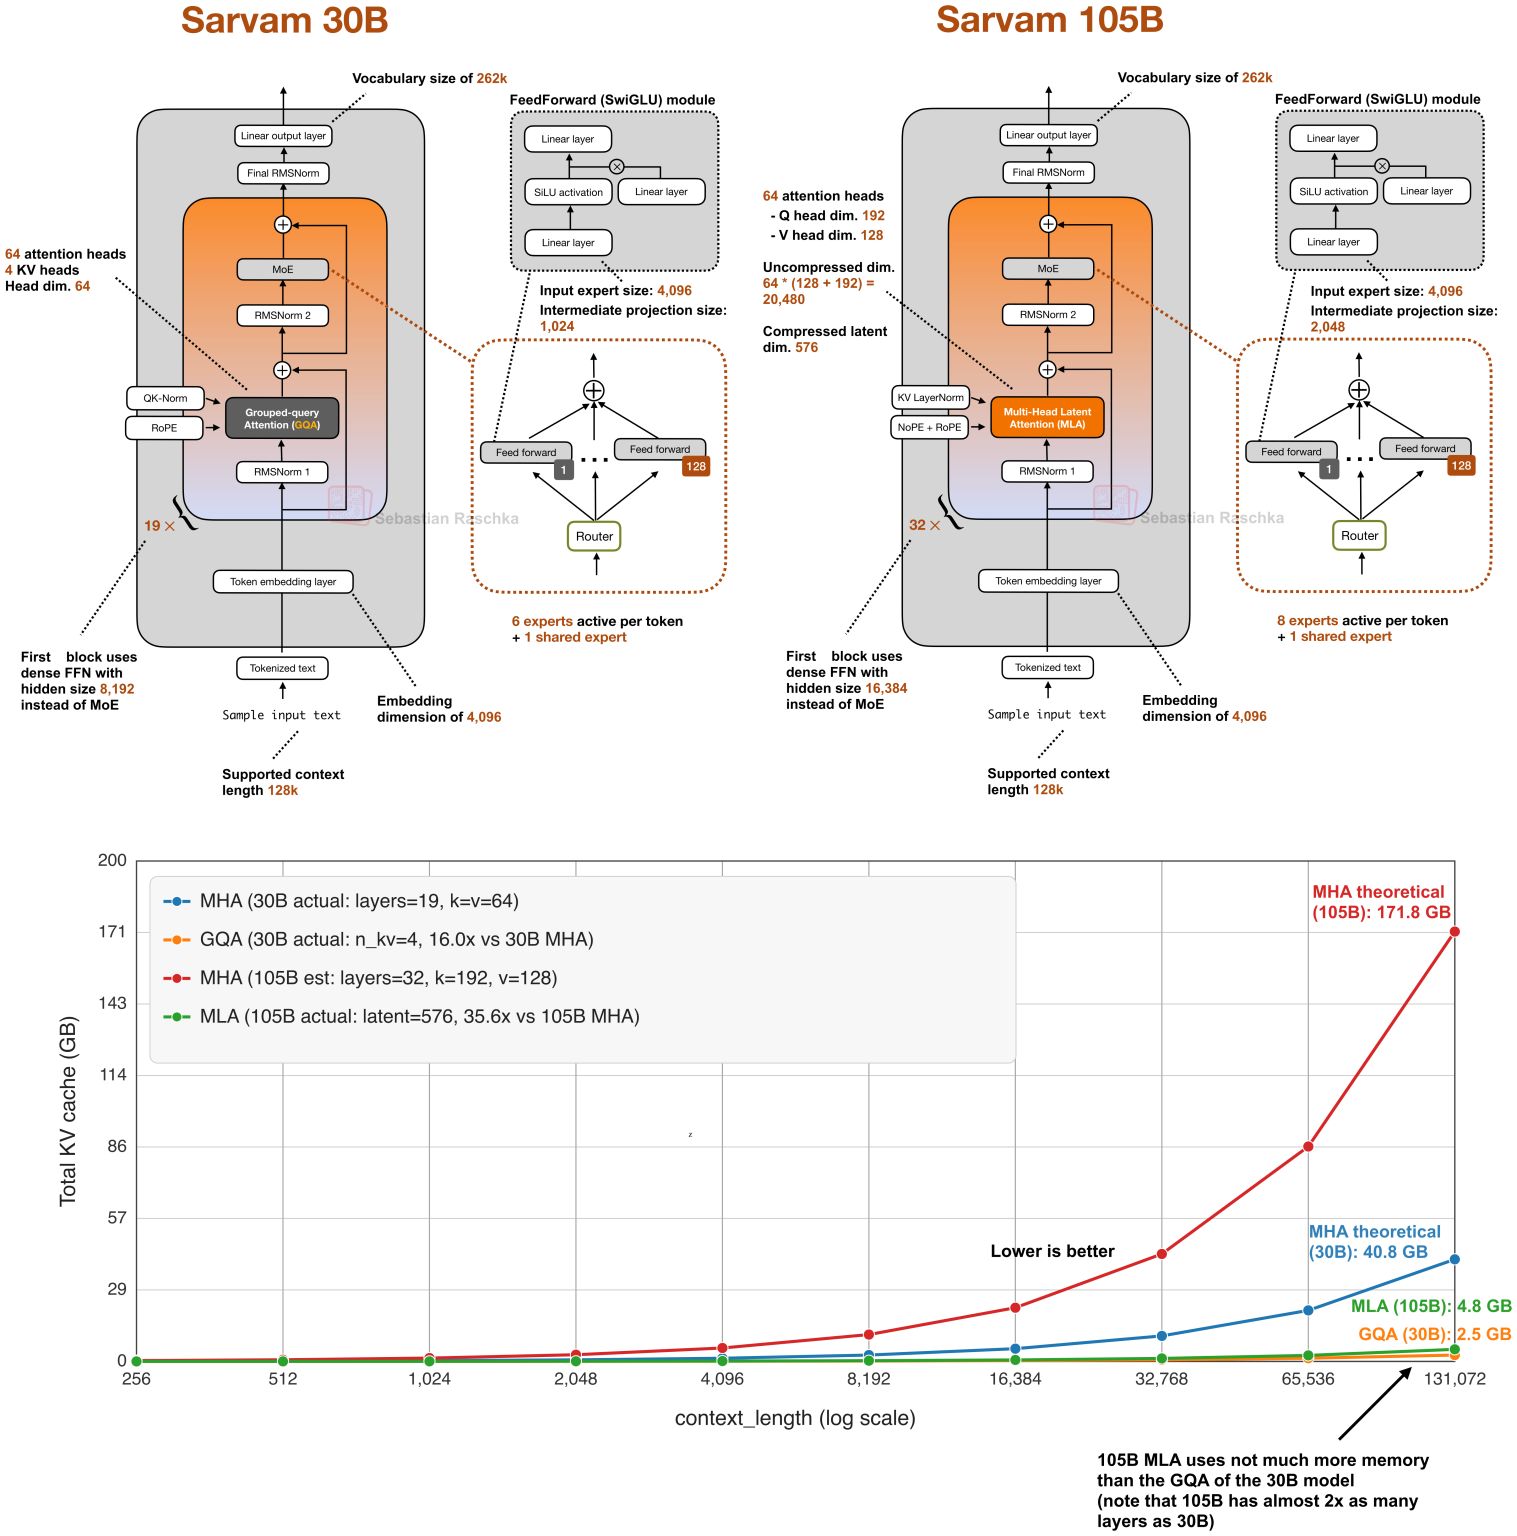
While waiting for DeepSeek V4 we got two very strong open-weight LLMs from India yesterday. There are two size flavors, Sarvam 30B and Sarvam 105B model (both reasoning models). Interestingly, the s…

I have been pretty heads-down this year to finish Chapter 6 on implementing reinforcement learning with verifiable rewards from scratch (using GRPO). I just finished it this weekend, and I'd say it's…

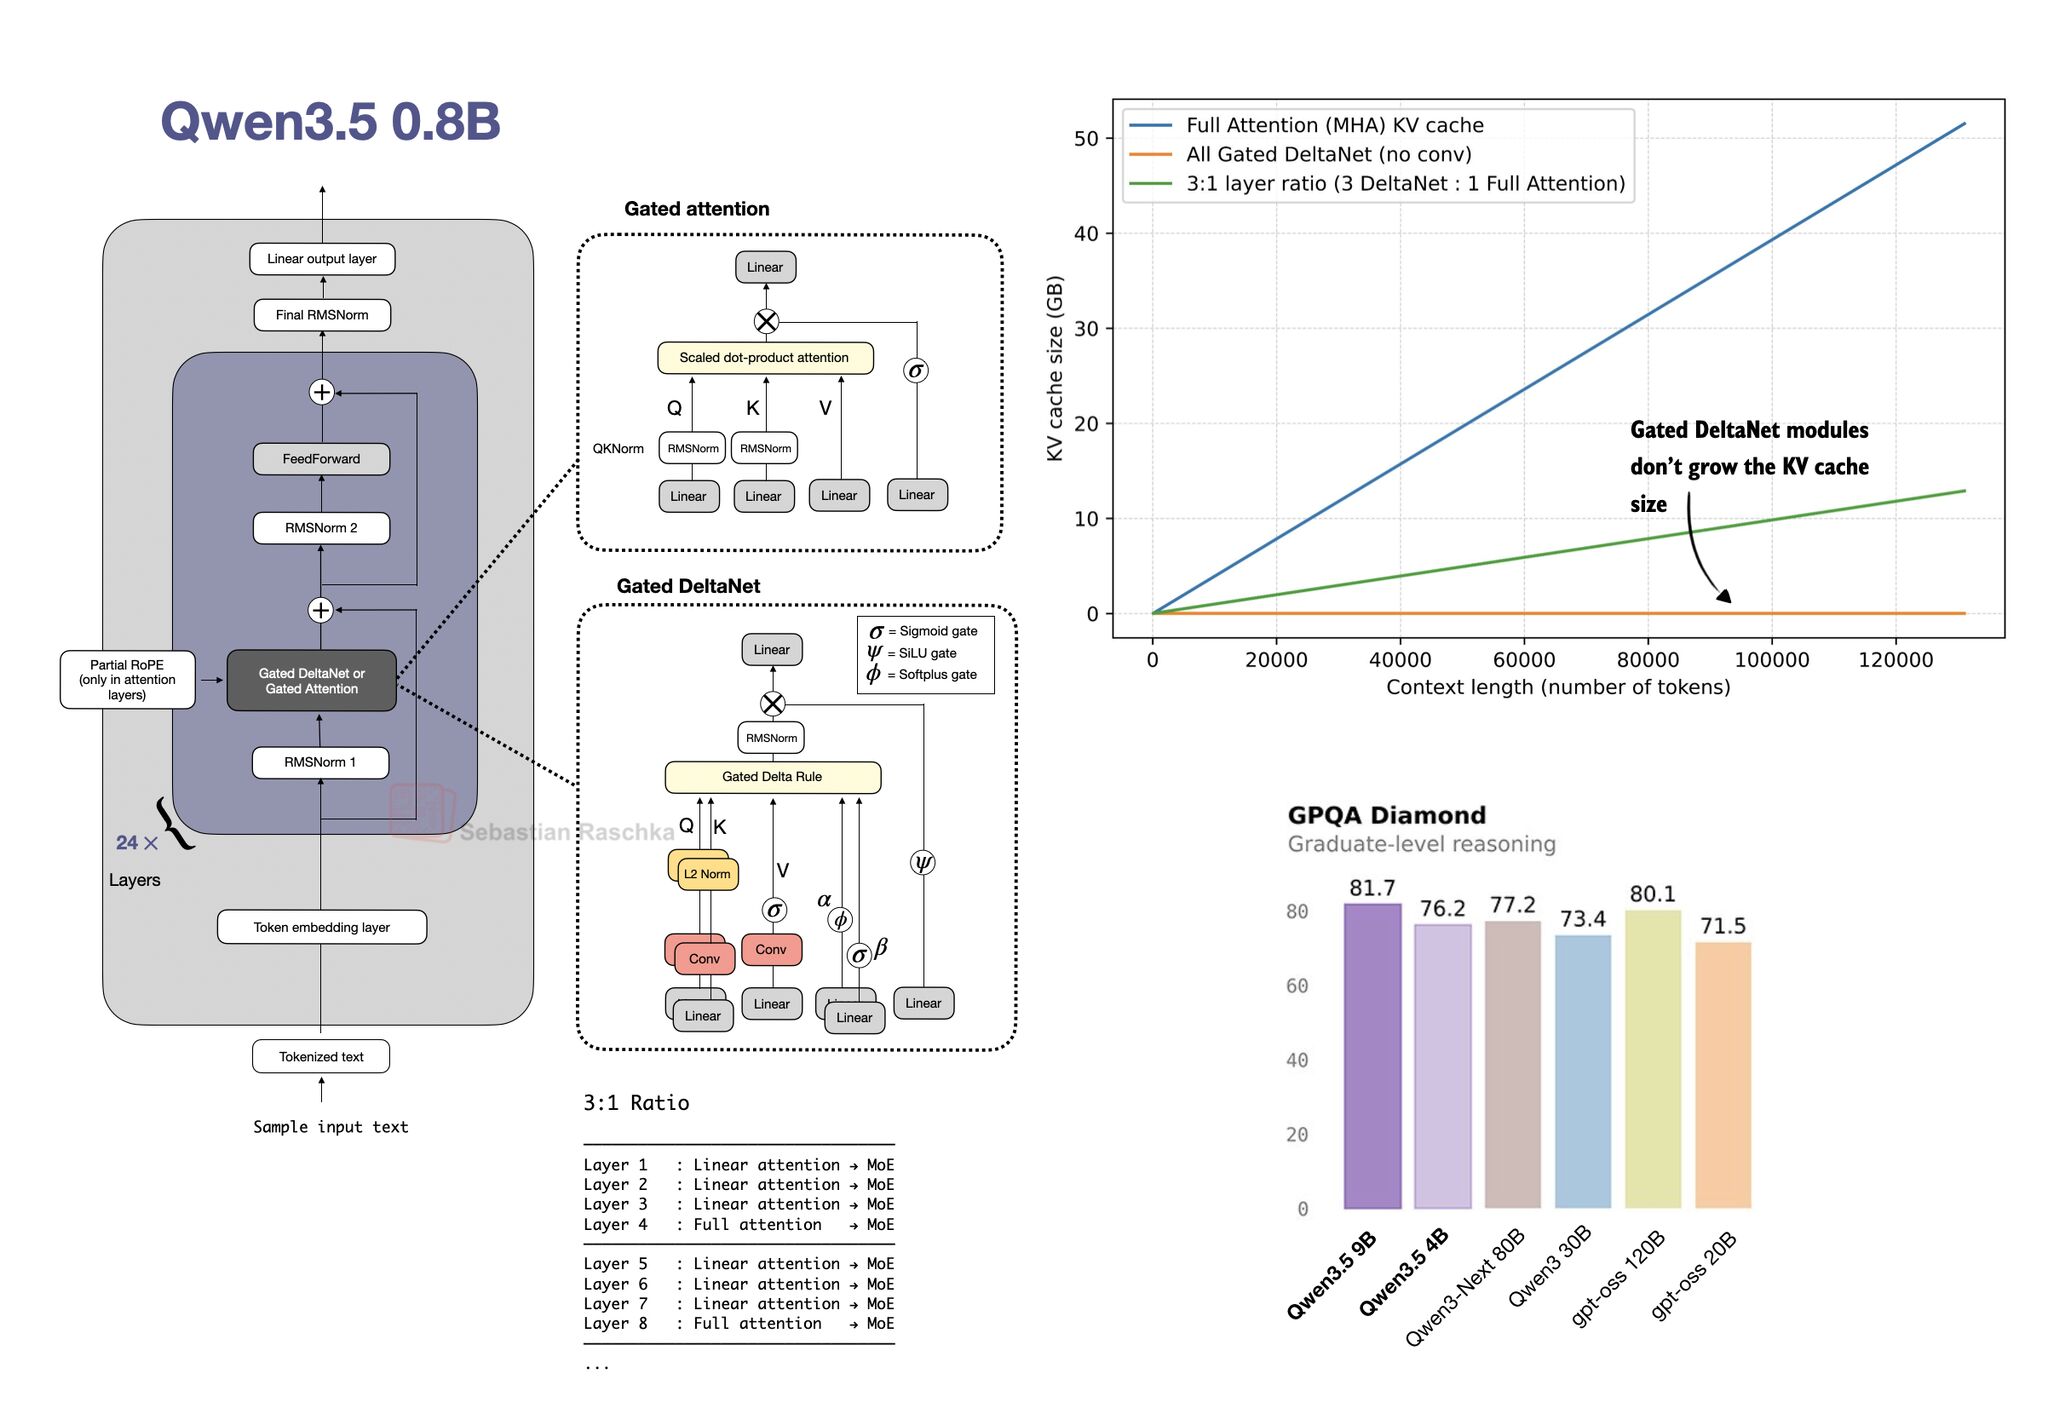
I coded up a Qwen3.5 from-scratch reimplementation for educational purposes. The full suite of smaller Qwen3.5 open-weight LLMs (0.8B, 2B, 4B, 9B) was released earlier this week, and it's probably the…

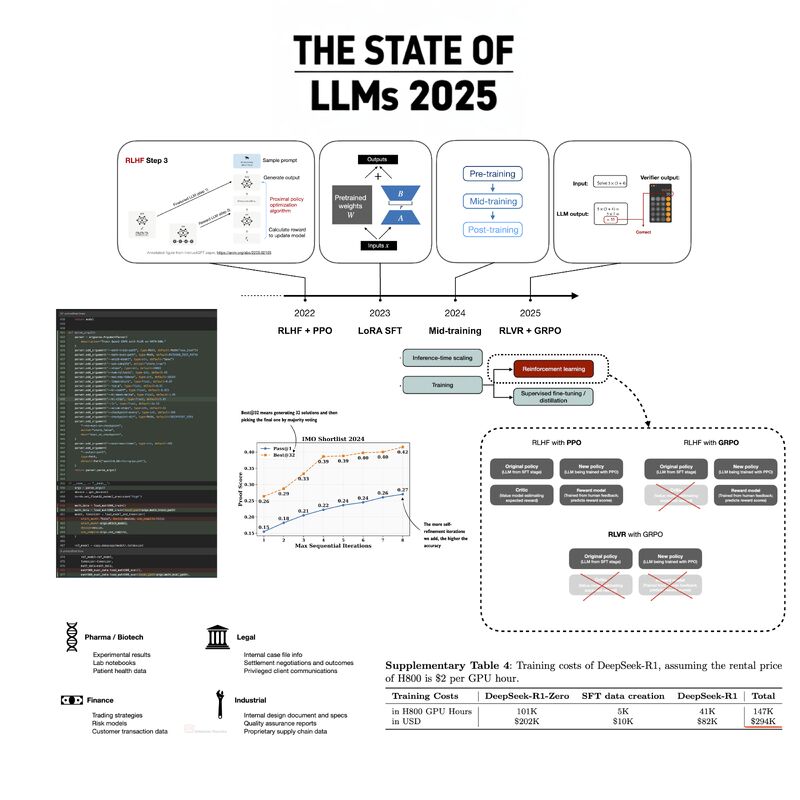
I just uploaded my State of LLMs 2025 report, where I take a look at the progress, problems, and predictions for the year. Originally, I aimed for a concise overview and outlook, but (like always) th…

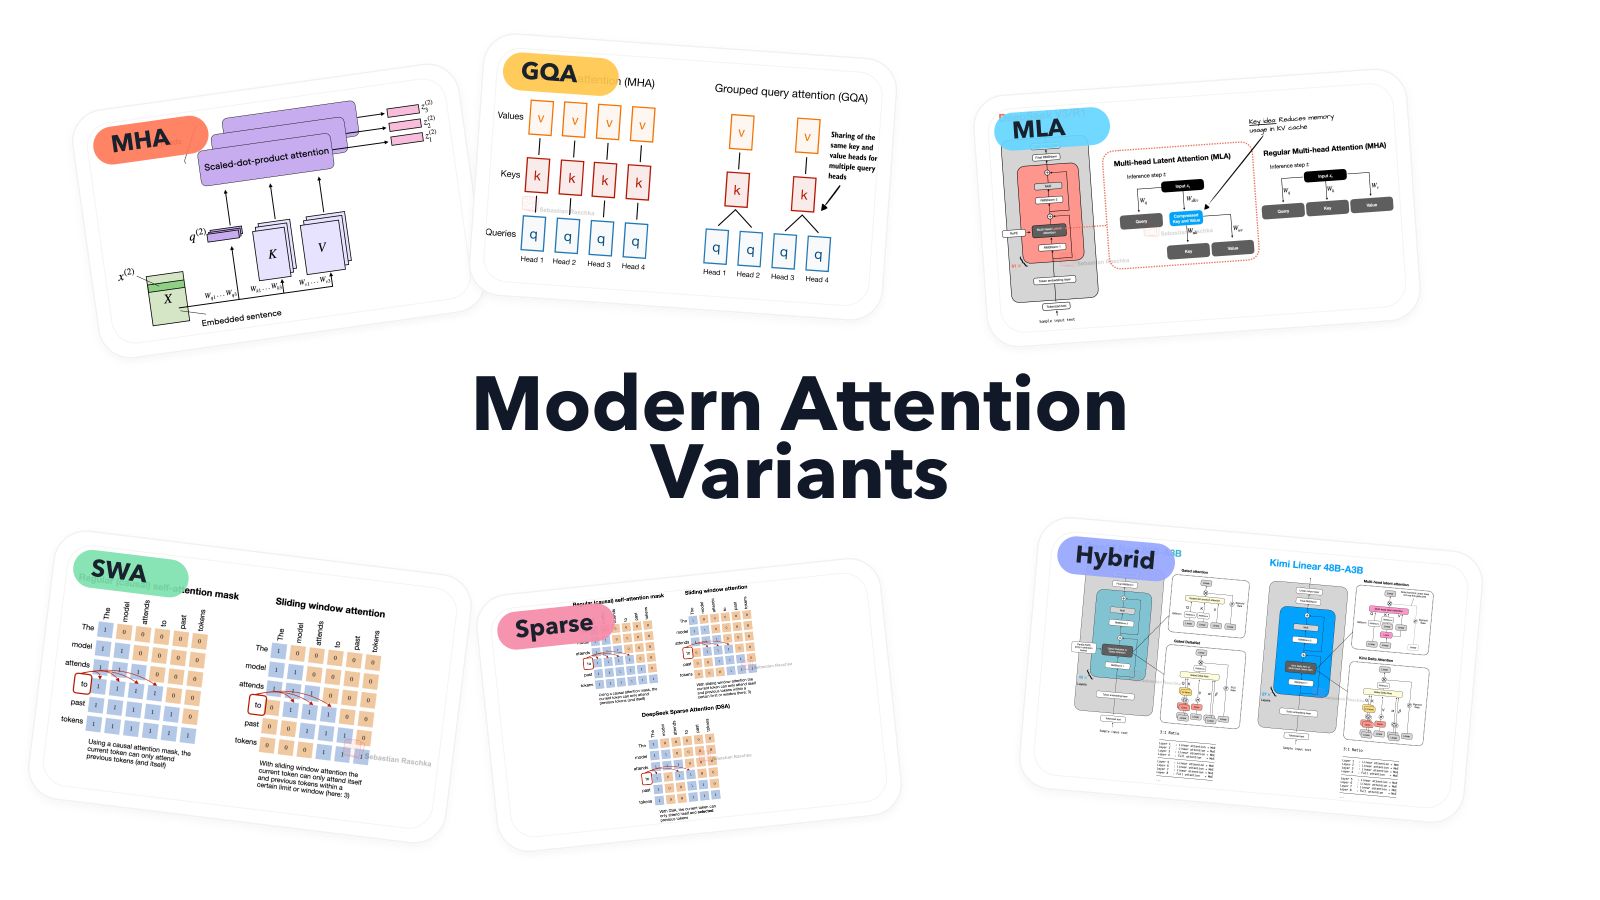
I put together a new visual guide to the main attention variants used in modern LLMs. What's (relatively new) is that once models moved to longer contexts, the design space widened quite a bit, and a…

1.7 posts/week
Posts / Week
4.7 days
Days Between Posts
7
Total Posts Analyzed
MEDIUM
Posting Frequency
2768.2%
Avg Engagement Rate
STABLE
Performance Trend
280
Avg Length (Words)
HIGH
Depth Level
ADVANCED
Expertise Level
0.88/10
Uniqueness Score
NO
Question Usage
0.25%
Response Rate
Writing style breakdown
<start of post>
I just finished a new deep-dive into the architecture of Qwen3-Next (the 235B MoE model). It's a massive release, and what's particularly interesting is how they've refined the "sparse" scaling laws we've been seeing lately.
Instead of just adding more experts, the team focused on the routing mechanism itself to ensure that the active parameter count (around 22B) stays efficient enough for reasonable inference throughput on H100 clusters.
Sign in to unlock the full writing analysis
Free tools to help you write, score, and benchmark in the same style.
Other creators worth studying alongside Sebastian Raschka, PhD.

Elliot Garreffa
Co-founder - Ghost Team | AI Agents, Automations & Apps in ChatGPT | Ex-Capgemini Invent
25 Viral Score

Jarno Duursma
LinkedIn Top Voice AI | Keynote speaker | Artificial Intelligence | 16 yrs experience | Future Focus | Tech Expert | Generative AI | ChatGPT | Deepfakes | Personal Growth | Spreker
44 Viral Score

Klaas Kroezen
Auteur van “Sales, oprecht en ontspannen” – Van klant naar fan met meer omzet & minder stress | Sales Excellence & Customer Success Training
151 Viral Score

Brian Balfour
Founder/CEO @ Reforge, Advisor @ Long Journey Ventures, Previously VP Growth @ HubSpot
36 Viral Score

Ross Stevenson
Chief Learning Strategist @ Steal These Thoughts! I help L&D Pros improve performance with tech + AI, and share lessons with 5,000 + newsletter readers.
35 Viral Score

Koen Stam
Leading International @Personio | Building community @Pavilion | Architecting Growth @Winning By Design | Showing revenue teams what’s next @GTM OS
22 Viral Score
ViralBrain plans, writes, and schedules your LinkedIn content, using official LinkedIn APIs so your account stays safe.
Write like Sebastian Raschka, PhD.