
I just built an advanced tutorial on how to use Claude Agent SDK. I'm giving it away at no cost to first 1000 developers. You'll learn the following: > Project Setup: Installing the CLI and initi…

6291.6K2349 viral
AI10 months ago
LinkedIn Content Strategy & Writing Style
Learn how to use coding agents in 5 mins a day | Building @ The Code Newsletter
1 person tracking this creator on ViralBrain
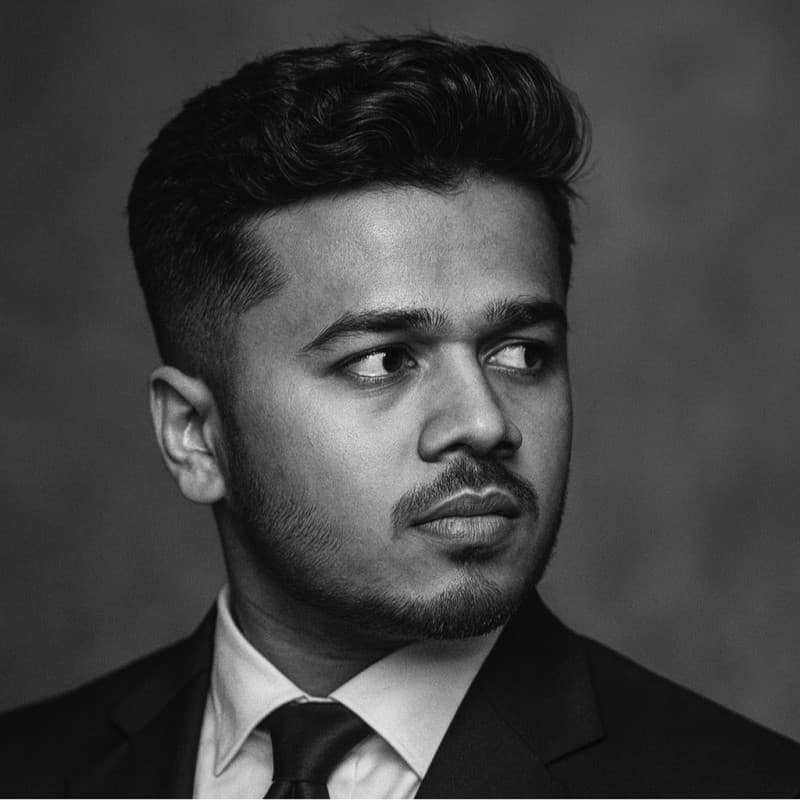
Om Nalinde positions himself as a practical guide to coding agents and frontier AI, translating fast-moving technical developments into five-minute daily lessons through The Code Newsletter. His content centers on agent infrastructure, model launches, memory systems, and deployment tradeoffs, often grounding big claims in concrete tools such as Python notebooks, Oracle Graph Memory, Nebius Token Factory, and Artificial Analysis benchmarks. He stands out by pairing accessible hooks, like the Jarvis comparison, with unusually sober evaluation of latency, cost, reliability, and workload fit. The intersection of technical education, product discovery, and sponsored analysis gives his work both broad reach and operational relevance.
159.0K
7.1K
48
5
21
I just built an advanced tutorial on how to use Claude Agent SDK. I'm giving it away at no cost to first 1000 developers. You'll learn the following: > Project Setup: Installing the CLI and initi…
This guy won the Anthropic hackathon and dropped the BIBLE of Claude Code. Everything you need. Nothing you don't. What's inside: Agents (13 total) → Plan features → Review code → Fix build errors…

You shouldn’t need to be an ML expert to have an ML idea. Today we’re launching ML Intern in HuggingChat 💬 Start with a conversation. Finish with deployable artefacts. 🔥 ML Intern lets you take a…
Why 𝗠𝗟 𝗽𝗿𝗼𝗷𝗲𝗰𝘁𝘀 teach you more about 𝗟𝗟𝗠𝘀 than LLM projects do Many people try to understand LLMs by building things with them: chatbots, RAG pipelines, agents. These are useful skills,…

"Maximizing the value of your Claude Code sessions" Agentic coding tools like Claude Code are incredible, but are you getting the most value out of your tokens? Anthropic's Lydia Hallie just dropped…
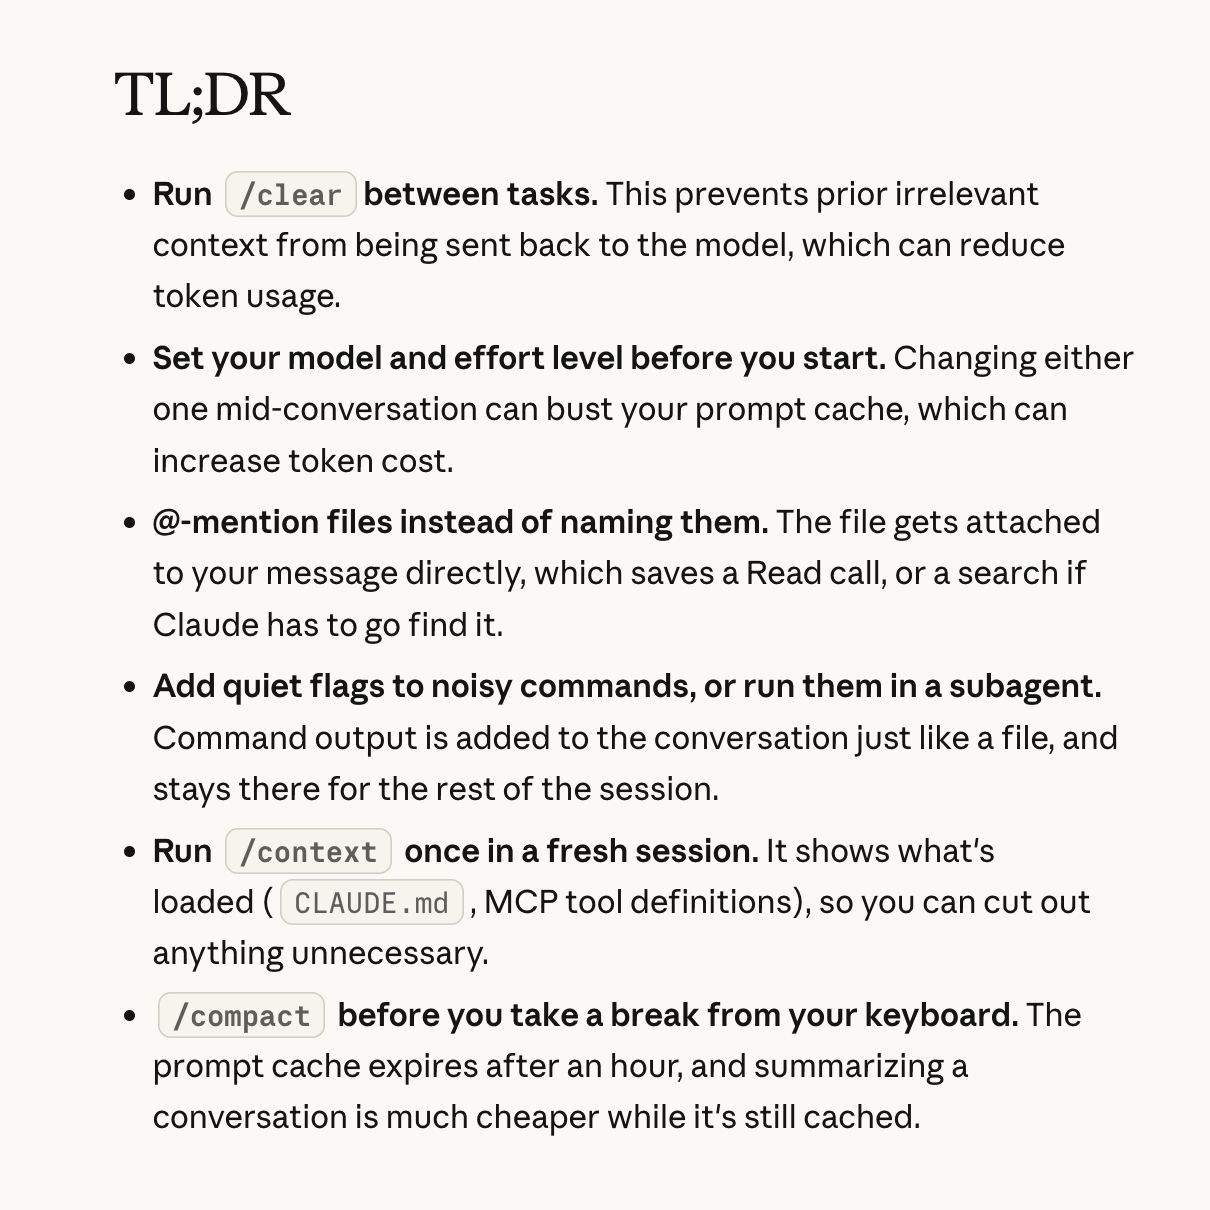
My engineering team compiled 100+ hacks for using Claude Code. They've been using Claude Code ever since it was launched and I think now is high time every developer starts using it! It includes:…

0.0 posts/week
Posts / Week
21
Total Posts Analyzed
LOW
Posting Frequency
47.67%
Avg Engagement Rate
STABLE
Performance Trend
140
Avg Length (Words)
HIGH
Depth Level
ADVANCED
Expertise Level
8/10
Uniqueness Score
YES
Question Usage
0%
Response Rate
Writing style breakdown
The following is a reconstructed standalone post designed to preserve the observed voice, structure, casing, punctuation, technical framing, contrastive reasoning, list density, and CTA behavior.
<start of post>
Most AI evaluations have a reliability problem nobody talks about: the happy path.
A model answers the demo question. A tool call succeeds once. A benchmark score looks strong.
Then the workload changes.
The prompt gets longer. The API times out. A retrieval result is technically relevant but operationally useless.
That’s why the next generation of agent testing is moving beyond answer quality.
Trace-level evaluation measures the full run, not just the final response
Tool-call validation checks whether the agent selected the right tool, passed the right arguments, and recovered when the tool failed
Scenario replay lets teams compare model, prompt, retrieval, and orchestration changes against the same workload
Failure clustering groups repeated errors by cause, so a team can fix a pattern instead of debugging every trace independently
Cost and latency budgets make quality measurable alongside the constraints that determine whether the system can actually ship
The part that matters most? Evaluation stays connected to the workflow. A correct answer that arrives too late is still a failed task. A cheap response that calls the wrong system is not efficiency.
The benchmark tells you what happened in one test.
The trace tells you why.
Teams should test the workload that matters: the messy requests, partial tool failures, stale context, ambiguous instructions and long-running tasks that production will eventually produce.
The model is only one variable. What the full system can do reliably is the product.
Try it here: https://example.com/agent-evaluation
<end of post>
Sign in to unlock the full writing analysis
Free tools to help you write, score, and benchmark in the same style.
Other creators worth studying alongside Om Nalinde.
Neil Patel
Co-Founder at Neil Patel Digital
4 Viral Score
Theo Browne
YouTuber & CEO @ T3 Chat (YC W22)
206 Viral Score

Philip Joubert
Building Magic Safari ✨
Ben Desjardins
Fractional CMO | I make Marketing work so you don’t have to | Founder, Sure Shot Systems | Marketing Brains + Ad Muscle | Grill Cheese Virtuoso 🥪 | Collecting passport stamps 🌍
23 Viral Score
Marta Basso
Entrepreneur | Founder @ Brandplane | Lilli Gruber Wannabe, basically a TV | Likely on a train while you’re reading this | 30k limit reached - send a note or use the follow button
5 Viral Score

Ester Martinez
Helping founders scale with intention | In service to a regenerative future
12 Viral Score
ViralBrain plans, writes, and schedules your LinkedIn content, using official LinkedIn APIs so your account stays safe.
Write like Om Nalinde.